24. Data Workflow Best Practices#
Attribution This lecture is designed based on great resources available on Earth Data Science Workflows from Earth Lab CU Boulder.
Identifying aspects of a workflow that can be modularized and tested can help you design efficient and effective data workflows.
24.1. Data Workflow Best Practices#
In the previous lessons, you designed a workflow to process several sites worth of Landsat data, but of course, identifying the workflow is just beginning.
For each of the steps you identified in your pseudocode, you need to flesh out how you can accomplish each task.
Before you design your workflow in more detail, there are many things to keep in mind regarding how you will use and name files, how you will modularize code to reduce repetitive code, etc.
Consider the data workflow best practices discussed below.
24.1.1. Do Not Modify the Raw Data#
Typically you do not want to modify the raw data, so that you can always reproduce your output from the same inputs. In some cases, this is less important, e.g., when you are not tasked with curating the raw data. For example you could re-download any Landsat data.
In other cases, this is extremely important - you wouldn’t want to recollect a summer’s worth of field collected data because you accidentally modified the original spreadsheet.
A good rule of thumb is to create an “outputs” directory where you store outputs. An outputs directory is helpful because:
You can always delete and recreate the outputs without worrying about deleting your original data.
An outputs directory is expressive and reminds anyone looking at your project (including you in the future - i.e. your future self!) where the output products are - they don’t have to dig for the data.
24.1.2. Create Expressive Intermediate File Names and Outputs#
You want to carefully consider how you name your intermediate and end product outputs so that the names reflect your intention and the content. For instance - in this case you are creating an NDVI dataframe which would be exported to a csv.
Here are some naming options:
# Less than ideal name
data.csv
# OK Name
ndvi.csv
# More expressive name
all-sites-ndvi.csv
Always use clear, expressive names for objects, files, etc. Ask yourself if someone reading your code could guess what is contained in that object or file based on the name.
24.1.3. Write Modular Code#
As you are working on your pseudo code, consider the parts of your analysis that are well suited for functions.
Writing custom functions for repetitive tasks in your workflows can help your workflow to be more efficient and easier to follow and implement.
Ideally, a Python function will have 1-3 inputs and will produce 1-2 outputs.
Keep functions small and focused. A function should do one thing well.
You can then combine many functions into a wrapper function to automate and make for a nicely crafted program.
You can use existing functions from commonly used packages (i.e. geopandas.read_file() or rasterio.open()) or write your own functions when one does not already exist.
24.1.4. Review of Key Components of Python Functions#
defkeywordFunction name
Input parameters/arguments
Docstring (that identifies parameters and returns)
returnstatement
Example of a simple function
def add_five(x):
    """
    Add the numeric value 5 to an input value.

    Parameters
    ----------
    x : int or float
        Input value.

    Returns
    -------
    int or float
        Input value increased by 5.
    """

    return (x + 5)
Now, check out the more complex geopandas.read_file() function on GitHub and identify each of the key components.
Do we have to fully understand all of the detailed code in order to use the function?
Simply put - no. We only need to know the appropriate inputs and outputs, so we can provide the correct file to get back our GeoDataframe.
This is one of the primary benefits of writing and using functions!
24.1.5. Benefits of Using and Writing Functions (Review)#
Reusability (e.g. by yourself or others)
Fewer variables (e.g. temporary variables not needed outside of the function are not stored)
Documentation/Reproducibility (e.g. for yourself or others)
Easier updates to code (i.e. update only the function definition)
Testing (e.g. include checks and tests on inputs and outputs directly within function)
Modularity (i.e. stand-alone units of code that can be executed and tested independently)
Sometimes you may need to write custom functions to:
complete tasks that do not already have published functions
combine existing functions into one function for a specific task
24.1.6. Generalizing Custom Functions#
The best functions complete one specific task but are generalizable for more than one application.
Example: Your goal is to write a function that can be used to calculate Normalized Difference Vegetation Index (NDVI)
(near_infrared - red) / (near_infrared + red)
How Can We Generalize This For Broader Use?
There are other indices that can be calculated using the same formula such as the Normalized Burn Ratio (NBR):
(near_infrared - shortwave_infrared) / (near_infrared + shortwave_infrared)
or Normalized Difference Water Index (NDWI):
(green - near_infrared) / (green + near_infrared)
Note that two different indices are commonly called NDWI: the one above (McFeeters, 1996) maps open water, while a second version (Gao, 1996) uses the near-infrared and shortwave infrared bands to measure the water content of vegetation. A general normalized difference function can calculate both.
So you can have a general function like:
(band1 - band2) / (band1 + band2)
Even better for conciseness and readability:
(b1 - b2) / (b1 + b2)
def normalized_diff(b1, b2):
    """
    Calculate the normalized difference of two arrays of same shape.
    Math will be calculated (b1-b2) / (b1+b2).

    Parameters
    ----------
    b1, b2 : numpy arrays
        Two numpy arrays of same shape.

    Returns
    -------
    n_diff : numpy array
        The element-wise result of (b1-b2) / (b1+b2) calculation.
    """
    n_diff = (b1 - b2) / (b1 + b2)

    return n_diff
24.2. Expand Code to Add Checks and Tests#
By including checks (i.e. tests) in your code, you can be more confident that your code is doing what you think it is!
Specific Reasons to Check Your Code
Check that inputs are of correct type/format (e.g. both arrays are two-dimensional)
Check that necessary prerequisites have been executed or exist (e.g. a directory named
output)Test assumptions of code (e.g. is it actually doing what you think it is?)
Identify points of failure (e.g. where is the code failing - input data, processing/analysis, writing out data?)
Identify something about the function that you did not consider (e.g. function is applicable to additional data types, function needs additional code to handle special circumstances)
How Can You Check Your Code?
There are many different ways to start checking your code. You can begin with conditional statements and work toward more complex checks using try/except and exception handling (which are introduced below).
24.2.1. Conditional Statements#
This is frequently referred to as “asking permission” before code can execute.
if condition_1:
    action_1
elif condition_2:
    action_2
else:
    action_3
Thinking about the normalized_diff function: what is a condition that we might want to check for the code to run successfully?
Take a look at the equation again, and think about what the intended inputs are for b1 and b2 (“arrays of same shape”).
(b1 - b2) / (b1 + b2)
import numpy as np

# Create numpy array inputs for function
nir_band = np.array([[6, 7, 8, 9, 10], [16, 17, 18, 19, 20]])
red_band = np.array([[1, 2, 3, 4, 5], [11, 12, 13, 14, 15]])

# Create three dimensional numpy array for testing
nir_band_3d = np.array([[[6, 7, 8, 9, 10], [16, 17, 18, 19, 20]]])


# Note that the if/else is used when calling the function
if nir_band_3d.shape == red_band.shape:
    ndvi = normalized_diff(b1=nir_band_3d, b2=red_band)
    print(ndvi)
else:
    print("Input arrays are not of same shape")
Input arrays are not of same shape
24.2.2. Try and except#
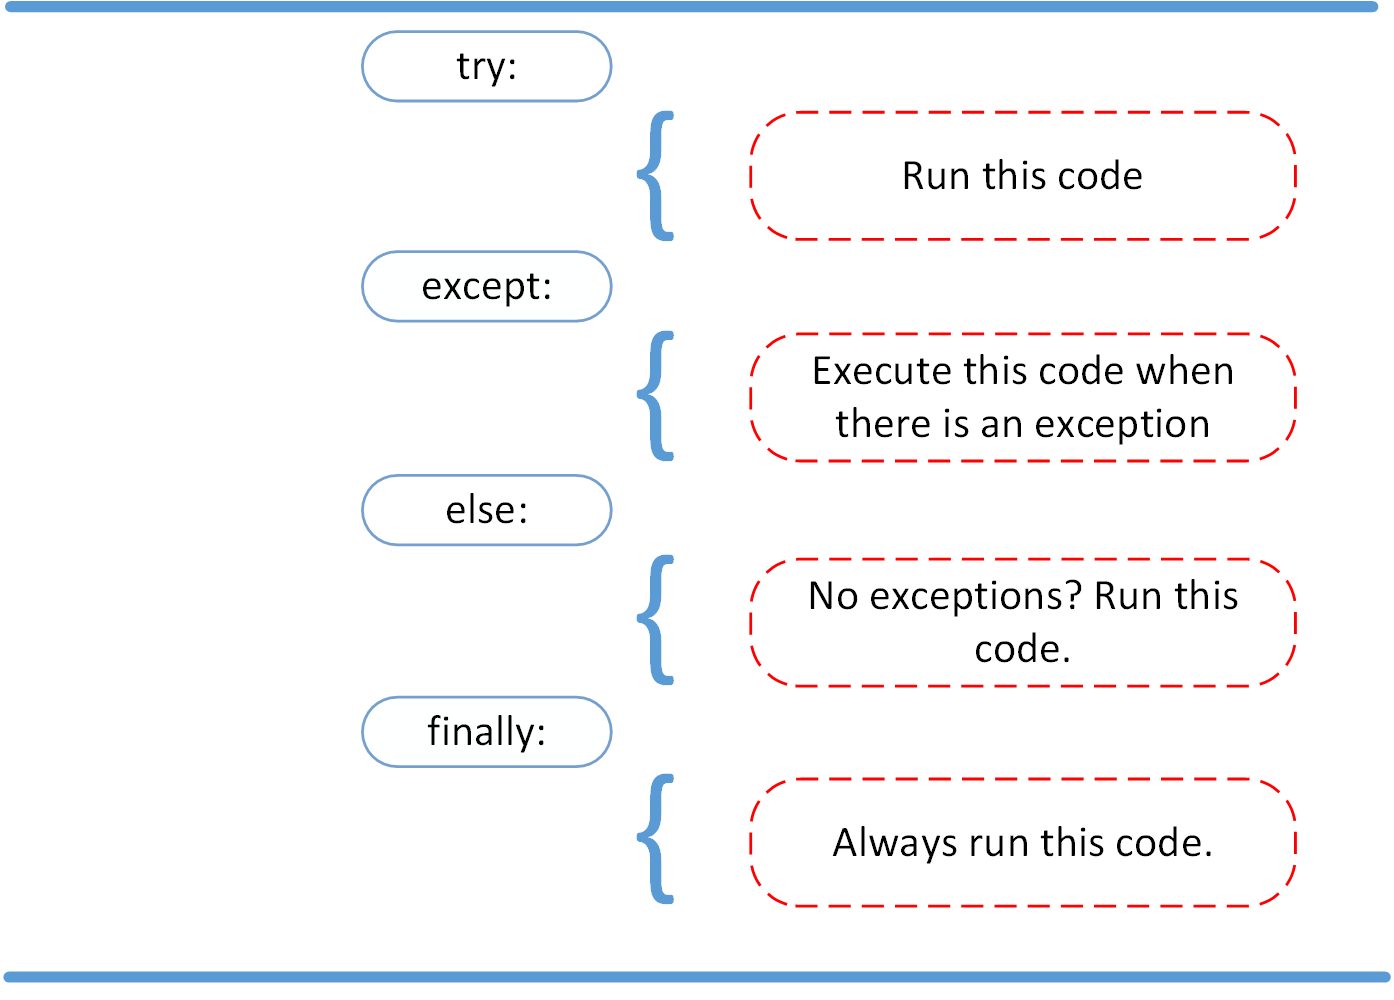
These statements allow a code block to try to execute first, and then do something else if the code is not executed successfully.
This is often referred to as “asking for forgiveness, rather than permission”.
Example of asking for permission:
x = 5
y = 0

if y != 0:
    print(x/y)
else:
    print("Division by zero not allowed!")
Division by zero not allowed!
Instead, ask for forgiveness:
try:
    print(x/y)
except:
    print("Division by zero not allowed!")
Division by zero not allowed!
You can also use try and except when calling a function:
# Create a red band with three rows (shape (3, 5)),
# which cannot be combined with nir_band (shape (2, 5))
red_band_3rows = np.array([[1, 2, 3, 4, 5], [11, 12, 13, 14, 15], [21, 22, 23, 24, 25]])

try:
    ndvi = normalized_diff(b1=nir_band, b2=red_band_3rows)
    print(ndvi)
except:
    print("Input arrays are not of same shape")
Input arrays are not of same shape
Note that we did not use nir_band_3d here. If you call normalized_diff(b1=nir_band_3d, b2=red_band), the function runs without any error:
ndvi = normalized_diff(b1=nir_band_3d, b2=red_band)
print(ndvi.shape)
(1, 2, 5)
NumPy broadcasts arrays whose shapes are compatible: it stretches the array of shape (2, 5) to match the array of shape (1, 2, 5). Broadcasting is very useful, but it also means that arrays of different shapes do not always cause an error. This is why an explicit check of the shapes (like the if statement above) is important when your function requires inputs of the same shape.
Caveat: Do you see any potential issues with try and except statements?
Let’s look at another example of try and except:
import os

directory = os.path.join(os.getcwd(), "exercise")

# Create folder if it does not exist
try:
    os.makedirs(directory)
    print("Directory created!")
except:
    print("Directory already exists!")
Directory created!
Caveat: How would you know that a failure to make a new directory was due to it already existing?
Is it possible that something else could cause a new directory to not get created?
24.2.3. Exception Handling#
Also commonly referred to as error handling, exceptions are used to check for specific types of errors that can occur when running code.
Though it is more common to use exception handling when writing code that you want to publish as packages or libraries or when you are writing applications for end users, it is useful to know about these, so that you are familiar with them when you receive exception messages from others’ code.
Commonly Used Exceptions:
Here is a selection of commonly used built-in Python exceptions with descriptions:
AssertionError: raised when the assert statement fails.
AttributeError: raised when the attribute assignment or reference fails.
EOFError: raised when the input() function meets the end-of-file condition.
FileExistsError: raised when trying to create a file or directory that already exists.
FileNotFoundError: raised when a file or directory is requested but does not exist.
ImportError: raised when importing the module fails.
IndentationError: occurs when there is a wrong indentation.
IndexError: occurs when the index of a sequence is out of range.
KeyError: raised when a key is not found in a dictionary (or a column name is not found in a pandas DataFrame).
KeyboardInterrupt: raised when the user interrupts a running program, by pressing Ctrl + C in a terminal or the interrupt (stop) button in Jupyter.
MemoryError: raised when programs run out of memory.
NameError: raised when a variable is not found in the local or global scope.
PermissionError: raised when trying to run an operation without the required access rights (e.g. writing to a folder you are not allowed to write to).
RuntimeError: occurs when an error does not fall into any of the other categories.
SyntaxError: raised by the parser when the Python syntax is wrong.
SystemError: raised when the interpreter detects an internal error.
TabError: raised when the indentations consist of inconsistent tabs or spaces.
TypeError: raised when an operation or function is applied to an object of the wrong type (e.g. adding a string and a number).
ValueError: occurs when the operation or function receives an argument with the right type but the wrong value.
ZeroDivisionError: raised when you divide a value or variable with zero.
Note that SyntaxError, IndentationError and TabError are raised when Python reads (parses) your code, before any of it runs. This means a try and except block in the same cell or file cannot catch them; you need to fix the code itself.
Also check here for the list of exceptions that can be raised by OS.
This is the same try and except with exception FileExistsError:
import os

directory = os.path.join(os.getcwd(), "exercise")

try:
    os.makedirs(directory)
    print("Directory created!")
except FileExistsError:
    print("Directory already exists!")
Directory already exists!
In practice, creating a directory only if it does not already exist is so common that Python has a built-in option for it. Setting exist_ok=True creates the directory if needed and does nothing if it already exists, while still raising an error for other problems (e.g. a PermissionError):
os.makedirs(directory, exist_ok=True)

# The same using the pathlib module
from pathlib import Path

Path(directory).mkdir(parents=True, exist_ok=True)
You could also explore error handling in your function definitions:
# Example of ValueError
def normalized_diff(b1, b2):
    """Calculate the normalized difference of two arrays of same shape.
    Math will be calculated (b1-b2) / (b1+b2).

    Parameters
    ----------
    b1, b2 : numpy arrays
        Two numpy arrays of same shape.

    Returns
    -------
    n_diff : numpy array
        The element-wise result of (b1-b2) / (b1+b2) calculation.
    """
    if not (b1.shape == b2.shape):
        raise ValueError("Input arrays should have the same dimensions")

    n_diff = (b1 - b2) / (b1 + b2)

    return n_diff
Now if you try to run the following code:
ndvi = normalized_diff(b1=nir_band_3d, b2=red_band)
You will see the following ValueError that can help you (and others) understand why the function did not execute successfully.
ndvi = normalized_diff(b1=nir_band_3d, b2=red_band)
---------------------------------------------------------------------------
ValueError                                Traceback (most recent call last)
Cell In[12], line 1
----> 1 ndvi = normalized_diff(b1=nir_band_3d, b2=red_band)

Cell In[11], line 17, in normalized_diff(b1, b2)
     13     n_diff : numpy array
     14         The element-wise result of (b1-b2) / (b1+b2) calculation.
     15     """
     16     if not (b1.shape == b2.shape):
---> 17         raise ValueError("Input arrays should have the same dimensions")
     18
     19     n_diff = (b1 - b2) / (b1 + b2)
     20

ValueError: Input arrays should have the same dimensions
24.2.4. Old Fashioned Trial and Error#
Maybe the code is executing just fine, but maybe you are not getting the output in the most optimal format.
It may not be clear to you until you run the function many times with different inputs.
# Create numpy array input for function
# Note that we are creating a zero in the denominator with -15
nir_band = np.array([[6, 7, 8, 9, 10], [16, 17, 18, 19, -15]])
red_band = np.array([[1, 2, 3, 4, 5], [11, 12, 13, 14, 15]])


# Produces infinity values due to divide by zero
ndvi = normalized_diff(b1=nir_band, b2=red_band)
print(ndvi)
[[0.71428571 0.55555556 0.45454545 0.38461538 0.33333333]
 [0.18518519 0.17241379 0.16129032 0.15151515       -inf]]
/tmp/ipykernel_267/3508432294.py:19: RuntimeWarning: divide by zero encountered in divide
  n_diff = (b1 - b2) / (b1 + b2)
In real satellite images, the most common cause of a zero denominator is nodata pixels, where both bands are 0. In that case the calculation is 0/0, which gives nan instead of inf (and NumPy warns about an “invalid value” instead of a “divide by zero”).
Trial and error can also reveal problems that do not produce any error or warning. Landsat bands are stored as unsigned 16-bit integers (uint16), which cannot hold negative numbers. See what happens when the red value is larger than the near-infrared value, which is common over water and bare soil:
# Landsat-like values stored as unsigned 16-bit integers
nir_uint16 = np.array([[3000, 4000], [2500, 6000]], dtype="uint16")
red_uint16 = np.array([[5000, 1000], [2000, 1500]], dtype="uint16")

print(normalized_diff(b1=nir_uint16, b2=red_uint16))
[[7.942      0.6       ]
 [0.11111111 0.6       ]]
NDVI must be between -1 and 1, but the first value is about 7.94. Because uint16 cannot store the negative result of 3000 - 5000, the subtraction wraps around to a large positive number (63536), and no error or warning is raised. The fix is to convert the inputs to floating point numbers before doing any math, which we include in the improved function below. (Applying the Landsat scale factor and offset also converts the values to float, but your function should not rely on its users remembering to do that.)
What if we would rather have the function return nan for any invalid values (such as infinity), and warn us when that happens?
import warnings

def normalized_diff(b1, b2):
    """
    Take two numpy arrays and calculate the normalized difference.
    Math will be calculated (b1-b2) / (b1+b2). The arrays must be of the
    same shape.

    Parameters
    ----------
    b1, b2 : numpy arrays
        Two numpy arrays that will be used to calculate the normalized difference.
        Math will be calculated (b1-b2) / (b1+b2). Integer arrays are converted
        to float before the calculation.

    Returns
    -------
    n_diff : numpy array
        The element-wise result of (b1-b2) / (b1+b2) calculation as a float array.
        Infinity values (from dividing by zero) are replaced with nan.
    """
    if not (b1.shape == b2.shape):
        raise ValueError("Both arrays should have the same dimensions")

    # Convert to float to avoid errors with unsigned integer data (e.g. uint16)
    b1 = b1.astype("float64")
    b2 = b2.astype("float64")

    # Ignore numpy's own warnings for division by zero, since we handle these below
    with np.errstate(divide="ignore", invalid="ignore"):
        n_diff = (b1 - b2) / (b1 + b2)

    # Set inf values to nan and provide custom warning
    if np.isinf(n_diff).any():
        warnings.warn(
            "Divide by zero produced infinity values that will be replaced with nan values",
            RuntimeWarning)
        n_diff[np.isinf(n_diff)] = np.nan

    return n_diff
Now, if you try the following:
ndvi = normalized_diff(b1=nir_band, b2=red_band)
print(ndvi)
[[0.71428571 0.55555556 0.45454545 0.38461538 0.33333333]
 [0.18518519 0.17241379 0.16129032 0.15151515        nan]]
/tmp/ipykernel_267/1485504021.py:35: RuntimeWarning: Divide by zero produced infinity values that will be replaced with nan values
  warnings.warn(
There is now a single warning provided by the function to explain that the division by zero resulted in values that are replaced with nan values, and the function returns a regular float array with nan where the result is invalid.
The function also handles the uint16 example correctly now:
print(normalized_diff(b1=nir_uint16, b2=red_uint16))
[[-0.25        0.6       ]
 [ 0.11111111  0.6       ]]
With an AI agent
Tests and checks are what make a coding agent useful. In the agentic loop (see Working with GenAI Tools), the agent runs your tests and keeps working until they pass, so your tests define what “correct” means. You decide what they check: before any implementation exists, write down the behaviors to test and the expected answers, worked out by hand from what you know about the domain (NDVI must be between -1 and 1, uint16 inputs must work, nodata pixels must become nan, inputs of different shapes must raise an error). An agent can then turn that plan into test code, but review every assertion, and make sure each test can fail: break the code on purpose (for example, remove the cloud mask) and check that a test catches it. This lecture is also your checklist for reviewing code an agent wrote. Does a bare except hide a real error? Does a function return different types for different inputs? Does the code write into the raw data folder? Put rules like these in AGENTS.md, and commit before every agent session so you can undo its changes. You will practice all of this in the lab.
There are many ways to include tests and checks in your code, so explore the resources below to learn different ways to incorporate them into your workflows.